
Explainable AI knowledge assistants with hybrid BM25 retrieval.
Lightweight AI knowledge assistant using BM25 retrieval and structured search without vector databases.
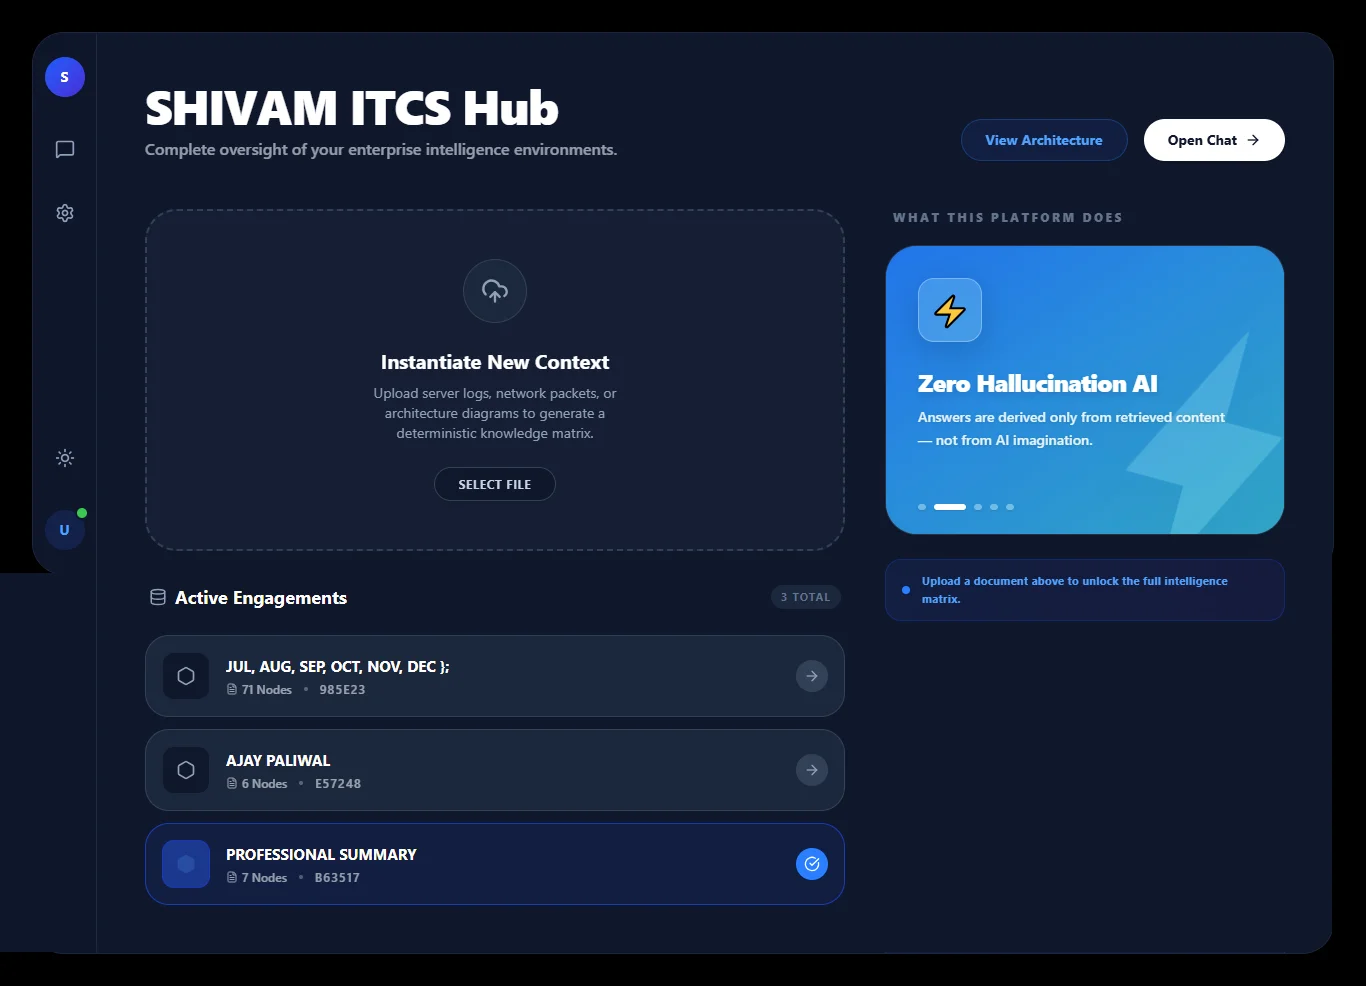
Application Interface & Screens
High-resolution production screens. Click any screen to open interactive full-screen zoom mode.
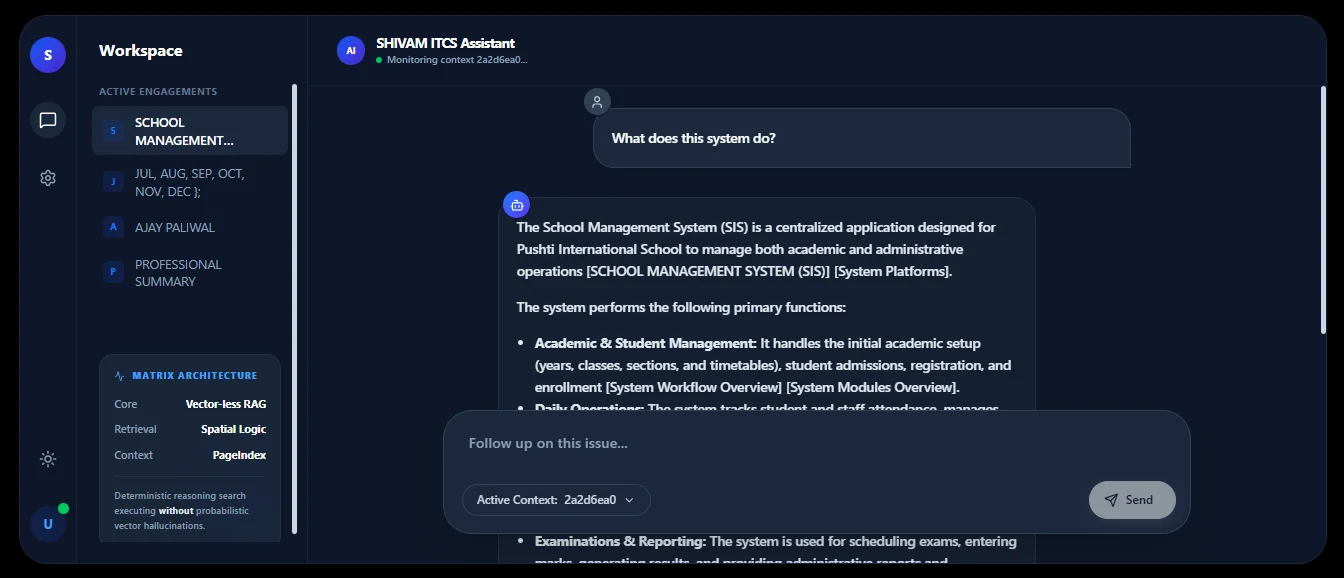
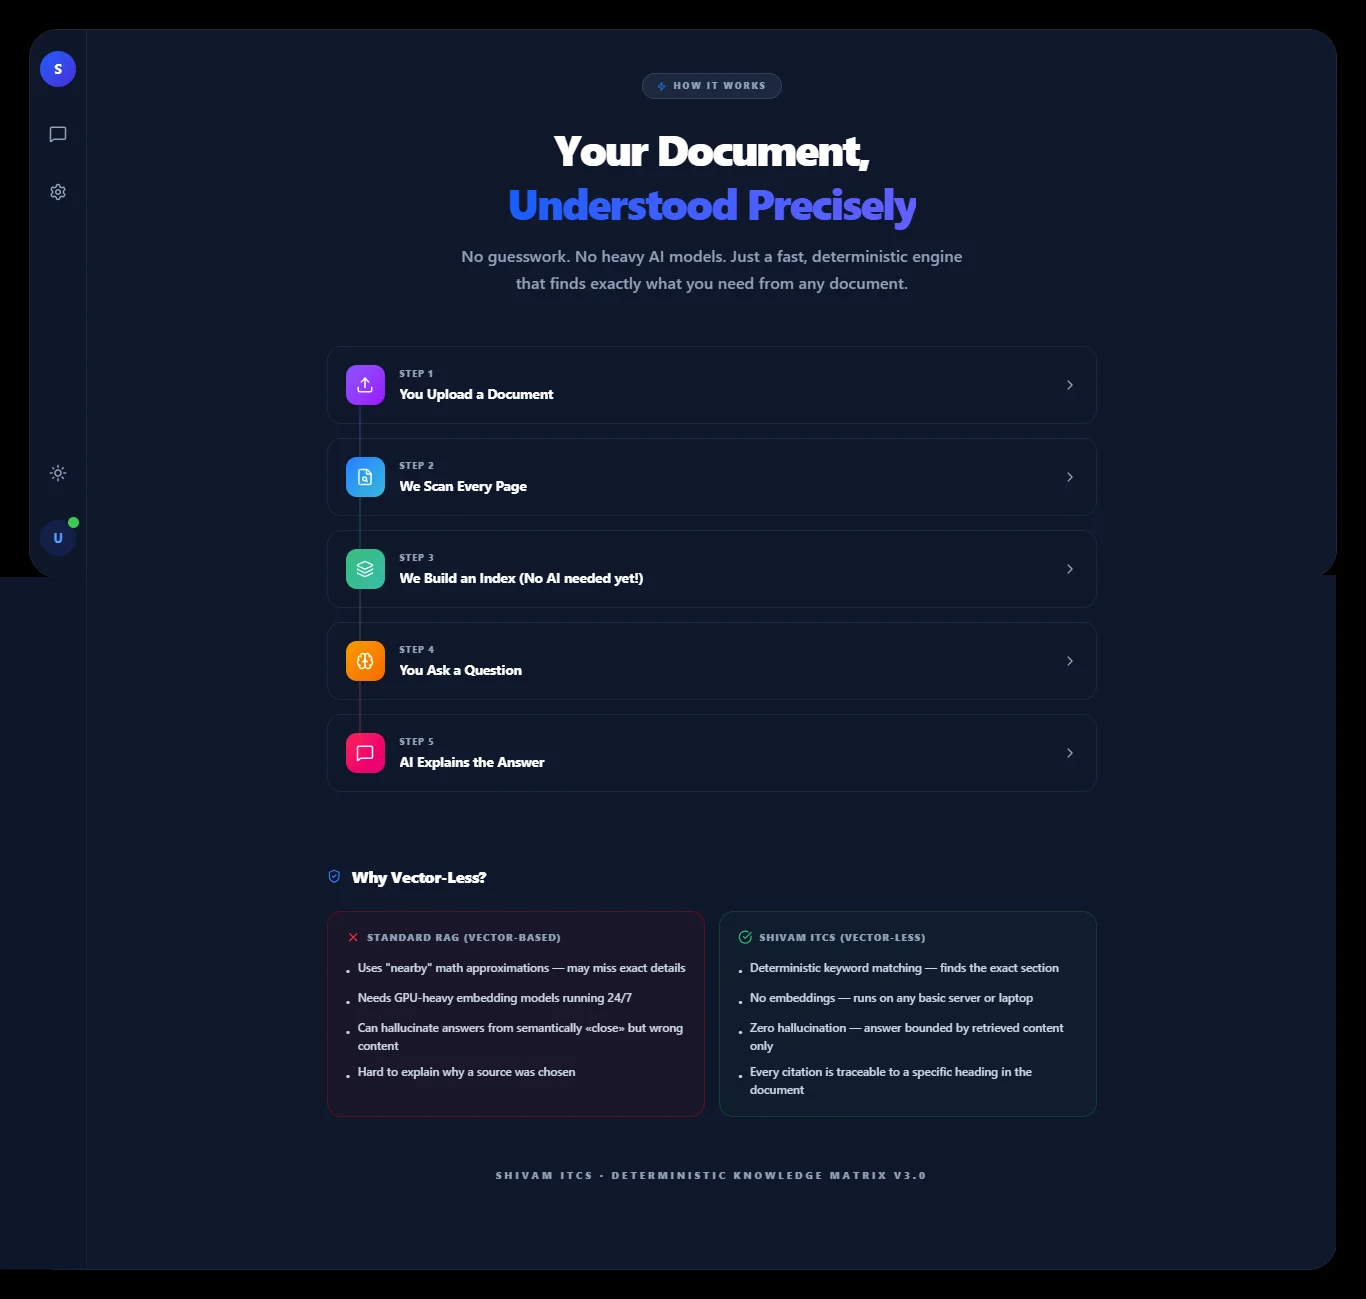
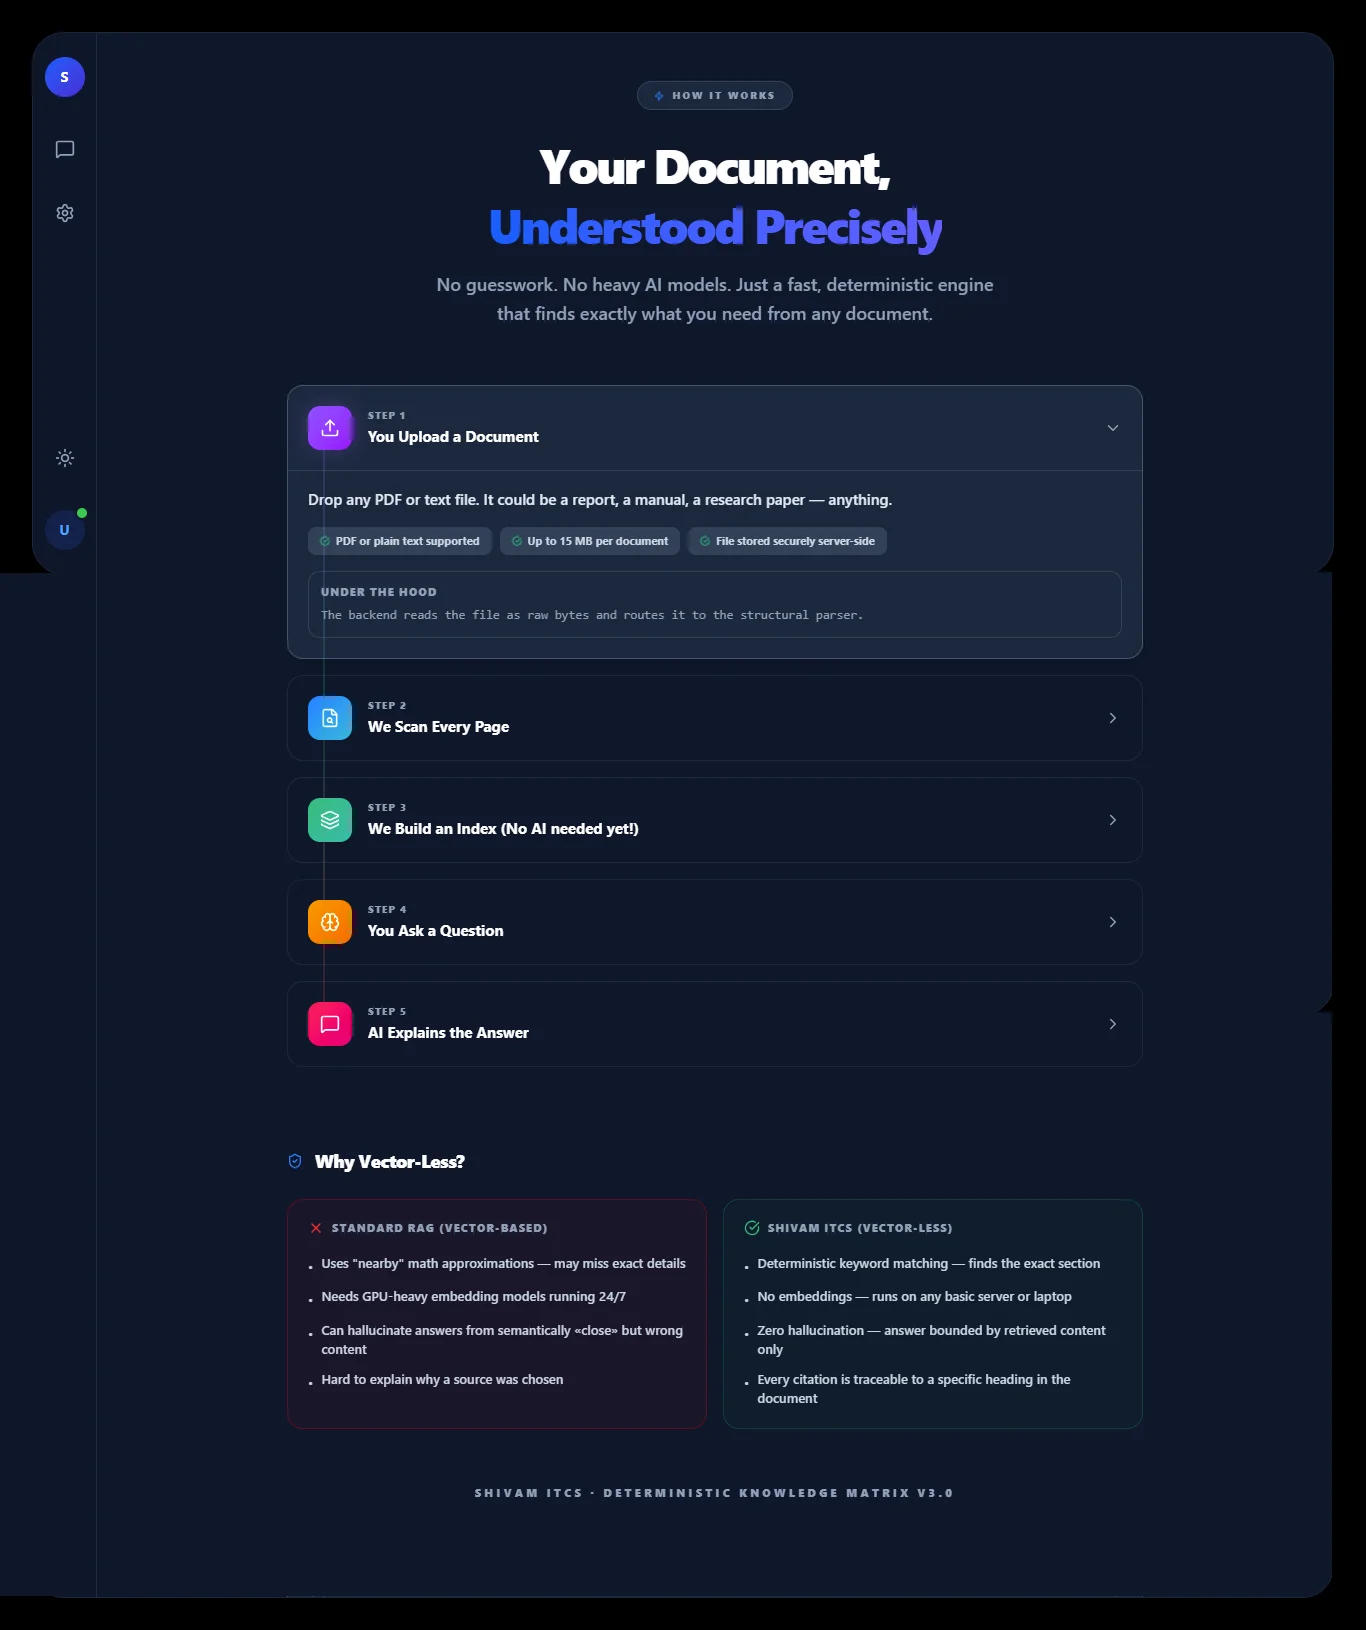
From Bottlenecks to Scalable Architecture
How we analyzed existing constraints and delivered a high-throughput, fault-tolerant platform.
Friction & Architectural Constraints
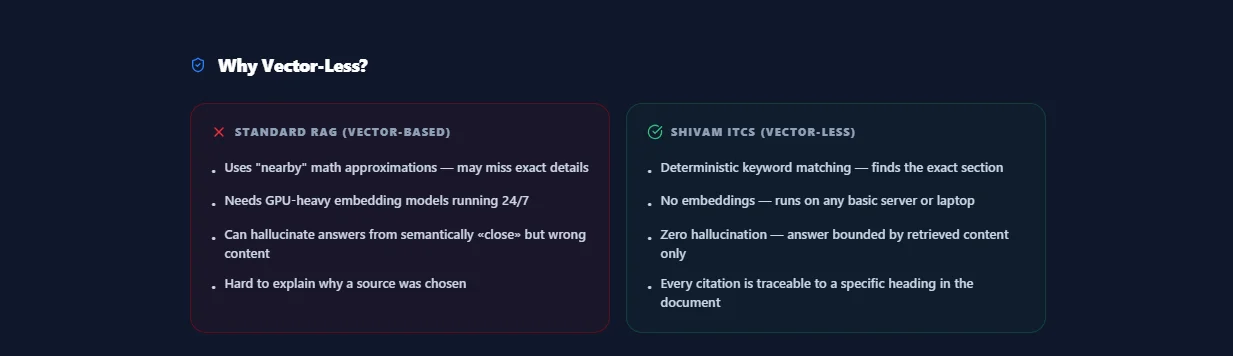
Traditional RAG systems rely heavily on vector embeddings and vector databases, increasing infrastructure complexity, operational cost, and latency while reducing explainability in production AI systems.
Autonomous Solution & Scale
Vectorless architecture using BM25 for keyword-based retrieval Structured knowledge storage using SQL databases LLM integration for contextual response generation Faster response time with reduced infrastructure overhead Explainable and deterministic response flow
System Highlights & Functionality
Key functionalities engineered for concurrency, high availability, and real-time execution.
Vectorless Retrieval (BM25)
Uses Elasticsearch/OpenSearch BM25 ranking for fast and accurate keyword-based search without vector embeddings.
Structured Knowledge Base
Stores and retrieves information using SQL databases and structured knowledge systems for consistency and control.
LLM Response Generation
Integrates OpenAI/OpenRouter APIs to generate contextual and human-like responses.
Low Latency & Cost Efficient
Eliminates vector database overhead to reduce infrastructure costs and improve response speed.
Explainable AI Flow
Deterministic retrieval provides traceable and understandable AI response generation.
Technology Stack & Production Metrics
Explore the quantified production KPIs, architectural benchmarks, and multi-tier technology frameworks powering this platform.
 Python
 FastAPI
 React
 Tailwind CSS
 Elasticsearch
 OpenSearch
 PostgreSQL
 MySQL
 Redis
 Nginx
Operational Video Walkthrough
Watch end-to-end user journeys, administrator backends, and live AI operations.
Vectorless RAG Walkthrough
Operational video demonstration for Vectorless RAG – Explainable AI Knowledge Assistant with BM25 Retrieval.
Looking to Build an Architecture Like This?
We design, architect, and deploy production-grade AI platforms, multi-tenant SaaS systems, and autonomous engines tailored for your enterprise.